Why IT systems slow down: how N+1 query patterns slow down web applications
IT performance problems often feel mysterious. Users complain that pages are slow, dashboards lag, and APIs time out, yet CPU and memory look normal. One common source of this hidden slowdown is repeated small queries. These are not large, complex reports. They are many tiny lookups that each add a network round trip and database work. Over a single page load, they accumulate into seconds of delay.
This article explains why repeated small queries happen, why they are harmful, and how N+1 query patterns slow down web applications in practice. It also shows simple ways to see the problem early and fix it before it becomes a systemic bottleneck.
Why repeated small queries create avoidable load
Modern web applications talk to databases, caches, search indexes, and microservices. Each call has overhead. Even a fast query on a fast database still needs serialization, network transit, scheduling, and result processing. When an endpoint fires ten or one hundred similar queries instead of one, the overhead multiplies.
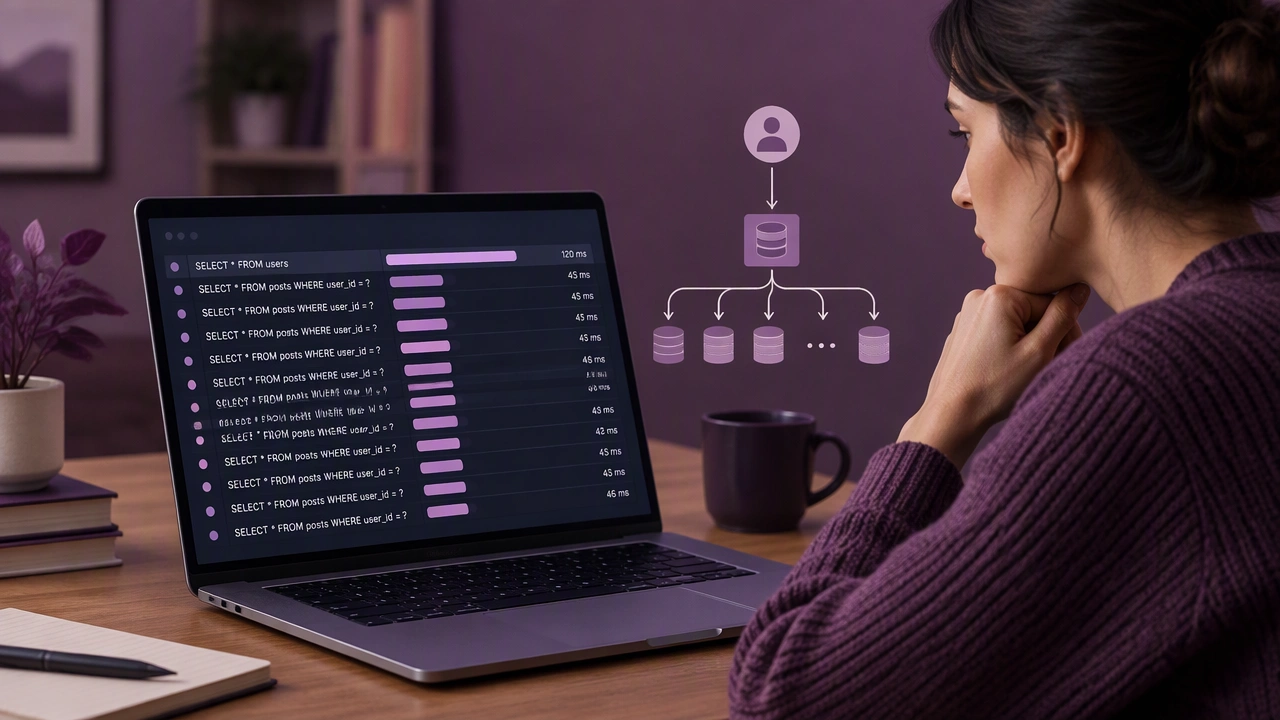
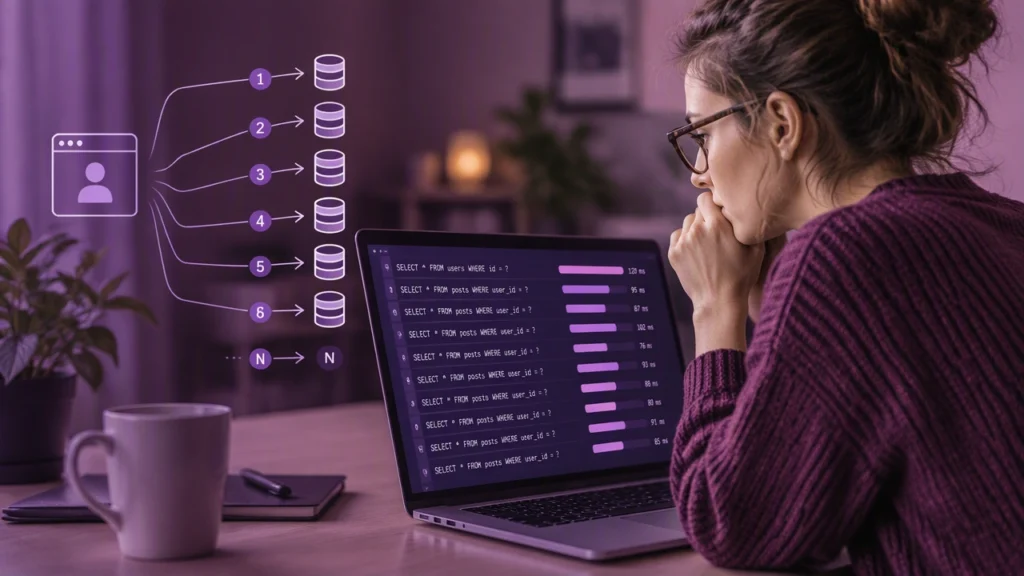
This is the core issue with N+1 query patterns. The application loads a list of N items, then for each item it runs one extra query to fetch related data. The result is N+1 round trips instead of a single batch call. The database may be healthy, but the application spends most of its time waiting on the network and on repeated parsing and planning.
How the pattern appears in real code
- ORM lazy loading: A developer loads a list of orders, then accesses order.customer in a loop. Each access triggers a query for the customer.
- Template rendering: A template iterates over posts and reads post.author.name, causing one query per author.
- REST or GraphQL resolvers: A list resolver returns items, and each nested field runs its own query in a resolver.
- Microservice fan-out: For each item, the app calls another service to get metadata, creating many small HTTP calls.
These patterns are easy to write and often work fine in development with small data sets. In production, with hundreds or thousands of rows, the cost becomes visible.
Why these patterns slow down web applications
The cost is not only the SQL text. It is the combination of many small effects that add up.
- Round-trip overhead: Each query adds latency from network and driver processing, even if the database returns in under a millisecond.
- Connection and thread pressure: Many queries hold connections and threads longer, reducing concurrency and increasing wait times under load.
- Planning and parsing: The database repeatedly parses and plans similar statements, increasing CPU usage.
- Lock and buffer contention: More operations increase the chance of contention on rows, pages, and internal structures.
- Caching misses: Repeated small queries often miss the application-level cache because they are not grouped or keyed efficiently.
Together, these effects raise response time, reduce throughput, and make scaling harder. The application consumes more resources for the same user action.
How to see the problem early
Detecting N+1 issues is easier when you measure the right things. The goal is to see repeated similar queries within a single request and to understand their cumulative cost.
1. Turn on query logging with context
Enable database query logs for development and staging. Include the request or trace ID, the query text, and the duration. Look for bursts of similar statements within one request. A pattern like many SELECT … WHERE id = ? or WHERE foreign_key = ? is a strong signal.
2. Use APM or tracing tools
Application performance monitoring tools can group queries by shape and show counts per endpoint. If a page runs the same statement hundreds of times, the tool will surface it. Distributed tracing can also show time spent in database spans versus application code.
3. Count queries per request
Add a simple metric: total queries executed during a request. Expose it in development and staging. Sudden spikes when data volume grows often reveal N+1 behavior.
4. Check for repeated similar statements
Compare query texts that differ only by parameter values. If many queries share the same structure and run in a loop, consider batching. Also watch for repeated reads of the same table in a single request.
5. Load test with realistic data
Run tests with production-like volumes. Small data hides N+1 costs. Larger lists expose them because the number of queries scales with the number of rows.
Practical ways to reduce the impact
Once you see the pattern, you can fix it with targeted changes. The goal is fewer round trips and better use of indexes and caches.
- Eager loading or joins: Fetch related data in one query using JOIN or ORM eager loading. This replaces N+1 queries with a single query that returns the needed rows.
- Batch queries: Collect the IDs in the list and run a single WHERE id IN (…) or WHERE foreign_key IN (…) query. This is helpful when joins are not practical.
- Prefetch for nested relations: For deeper graphs, use multi-level prefetch to load children and grandchildren in a small number of queries.
- Result caching: Cache frequent lookups such as user or product metadata. Use clear keys and short TTLs to avoid stale data.
- Read models or materialized views: For heavy pages, build a read model that precomputes the needed shape, reducing runtime queries.
- Streaming and pagination: Avoid loading huge lists in one view. Paginate or stream results to keep query counts predictable.
A simple checklist for code review
- Is the list loader also fetching related data in one query?
- Are loops performing queries or HTTP calls per item?
- Do templates access relations that are not loaded?
- Do resolvers batch or cache cross-service calls?
- Do metrics show high query counts for list endpoints?
When to optimize and when to wait
Not every N+1 case needs immediate action. If an endpoint serves a small list with low traffic, the impact may be negligible. Prioritize fixes where query counts scale with data volume, where traffic is high, or where latency targets are strict. Use measurement to guide decisions, not guesses.
Summary
Repeated small queries are a common and avoidable source of slowness in IT systems. They add round trips, increase contention, and waste resources. By learning how N+1 query patterns slow down web applications, teams can detect the issue with logging, tracing, and simple metrics, then fix it with eager loading, batching, caching, and better data access design. The result is faster pages, lower database load, and a system that scales more gracefully.