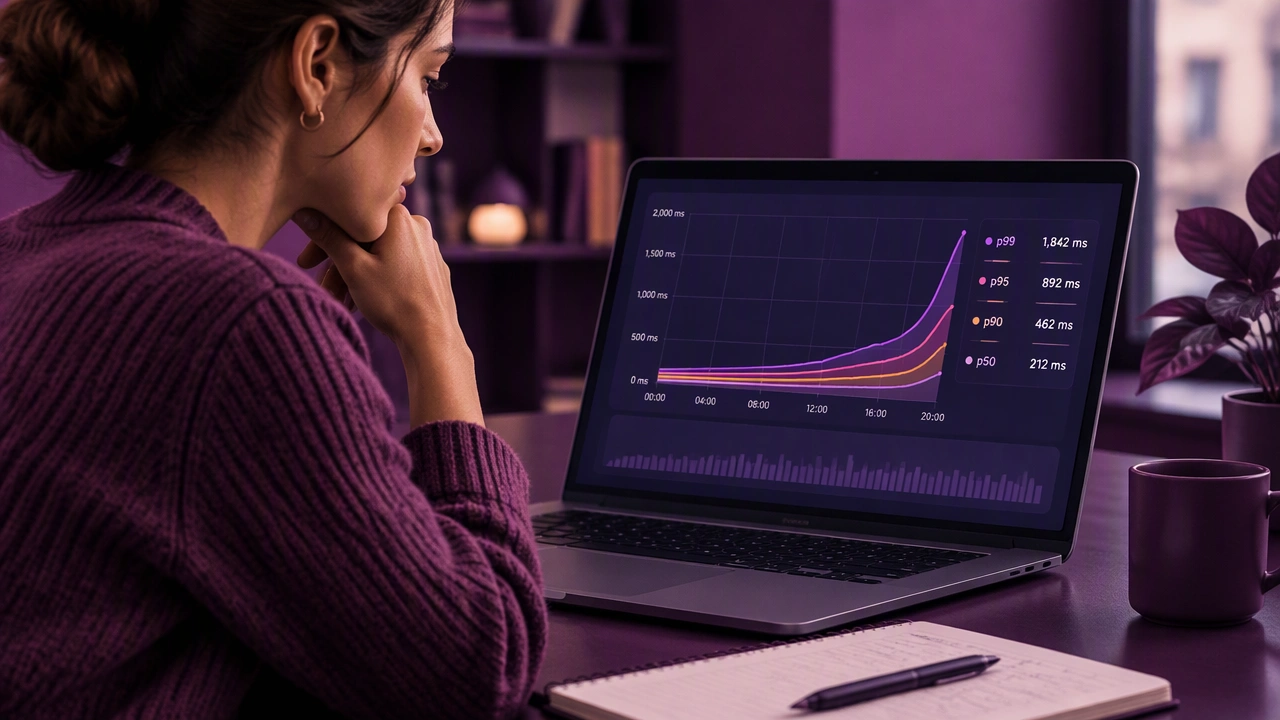
Why IT Systems Slow Down: How to Read Latency Percentiles Instead of Averages
IT performance often looks healthy in a dashboard until users complain. The charts show an average response time that barely moves, yet some customers wait several seconds for the same page or transaction. This gap is common because averages flatten differences. Learning how to read latency percentiles instead of averages is a practical way to see the slow experiences that summary numbers hide.
Averages describe the middle, not the worst moment
An average adds up all observed response times and divides by the number of requests. It gives one number that is easy to share, but it can be strongly influenced by many fast requests. If most requests finish quickly and a smaller group waits a long time, the average may still appear reasonable.
Consider a service that handles 10,000 requests. Nine thousand finish in 100 milliseconds, while one thousand take 3 seconds. The average is about 390 milliseconds, which sounds acceptable to some teams. Yet one in ten users experiences a three-second wait. The average does not show that split; it only describes the overall center of the data.
Slow requests matter because users do not experience an aggregate. Each person sees the result of one request. A system can meet an average target while still creating a frustrating experience for a meaningful group of customers.
What latency percentiles show
A percentile tells you the value below which a chosen percentage of observations falls. If the 95th percentile latency is 2 seconds, then 95 percent of requests completed in 2 seconds or less, while 5 percent took longer. The percentile makes the tail visible instead of blending it into a single mean.
Common choices are the median, p90, p95, and p99. The median is the 50th percentile: half of the requests were faster and half were slower. p90 describes the slowest 10 percent boundary, p95 the slowest 5 percent, and p99 the slowest 1 percent. Higher percentiles focus on rarer but more painful waits.
Percentiles are especially useful when traffic is mixed. A service may serve quick API calls and slower report requests through the same endpoint. The average can move because the traffic mix changes, even when no individual path becomes slower. Percentile bands help separate a general slowdown from a change in the number of heavy requests.
Reading a percentile view in practice
Start by looking at several percentiles together rather than one number. A useful dashboard might show p50, p95, and p99 for the same endpoint over the same time window. The median shows the typical request, while p95 and p99 show how bad the tail becomes.
Look for patterns across the three lines:
- All percentiles rise together: the service may be under broad pressure, such as CPU saturation, a slow dependency, or a network problem.
- p50 stays flat while p95 and p99 rise: a subset of requests is hitting a slow path, such as cache misses, large payloads, or a particular shard.
- p99 spikes briefly: short bursts may come from garbage collection, connection pool waits, autoscaling, or a temporary downstream timeout.
- The gap between p50 and p99 widens: variability is increasing, even if the typical user still sees good performance.
These patterns are clues, not conclusions. Percentiles show where to investigate; they do not identify the cause by themselves.
Choose percentiles that match the user impact
No single percentile is correct for every system. The right choice depends on how many slow requests the product can tolerate and how many users are affected.
For an internal tool with low traffic, p95 may be enough to catch noticeable delays. For a large consumer service, p99 can represent tens of thousands of requests per minute, so a problem at p99 still affects many people. For payment or authentication flows, teams often watch p95 and p99 together because both reliability and tail latency matter.
It also helps to set targets as service objectives. For example, a team might state that 95 percent of requests should complete within 500 milliseconds and 99 percent within 1.5 seconds. This makes the expected experience explicit and prevents a good average from masking a bad tail.
Measure the whole journey, not only one service
A user request often crosses several services, caches, databases, and queues. Fast internal operations can still produce a slow end-to-end result when one dependency waits or retries. Measure latency at the edge where the user waits, then compare it with timings from each hop.
Trace the same request across components when possible. A trace can show that a service spent 80 milliseconds on its own work but waited 1.2 seconds for a database connection. Percentiles help identify which requests deserve a trace; the trace explains where the time went.
Keep the measurement window consistent. A p95 calculated over one minute can be noisy when traffic is low, while a very long window can hide short incidents. Pair percentile charts with request volume and error rate so changes in traffic do not create misleading conclusions.
Common mistakes when using percentiles
Teams sometimes average percentile values across hosts or time buckets. This produces a number that is difficult to interpret. Percentiles should be calculated from the underlying observations or combined with a method designed for distributions, not simply averaged.
Another mistake is watching only p50. The median is valuable, but it says nothing about the slowest requests. The opposite mistake is to focus only on p99 and ignore the median, which can hide a broad slowdown affecting everyone.
Finally, remember that percentiles describe latency, not causation. A sudden p99 increase might be caused by a deploy, a dependency outage, or a change in request size. Use deployment markers, infrastructure metrics, and traces to connect the tail movement to an event.
A clearer way to discuss performance
Percentiles give teams a shared language for discussing user experience. Instead of debating whether 400 milliseconds is good, they can say that half of requests finish quickly while 5 percent exceed a threshold that customers notice. This framing connects technical measurements to real outcomes.
Start with the median to understand the typical path, then add p95 and p99 to expose the bad experiences. Watch how the bands move over time, compare them with traffic and errors, and use traces to investigate the slow tail. This simple practice makes hidden delays visible and helps IT teams fix the problems that averages conceal.