IT Performance and the Hidden Tax: Why Small Network Delays Multiply Across Every Request
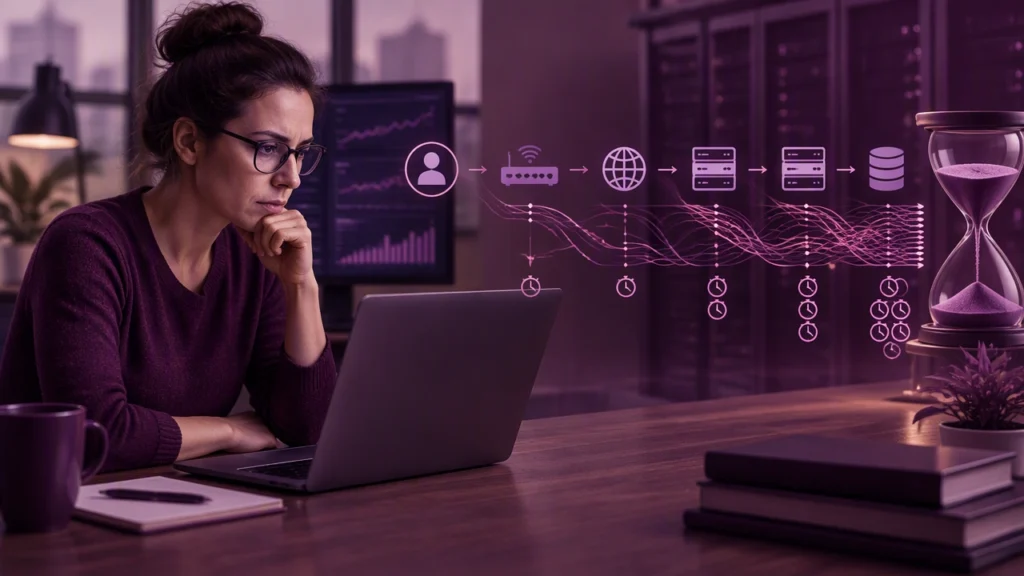
Modern applications rarely run on a single machine. A single user request often touches a web server, an API gateway, one or more microservices, a database, a cache, an identity provider, and several third-party APIs. Each of those hops crosses a network boundary, and each network boundary introduces latency. The result is a pattern that quietly degrades IT performance: small, individually acceptable delays accumulate into noticeable slowdowns that affect users, revenue, and reliability.
This is why how network latency adds hidden cost to every user request is one of the most important questions for platform teams, SREs, and backend engineers. The slowdown is not always caused by a broken component. It is often caused by the compounding effect of many small waits.
Why small network delays feel bigger than they sound
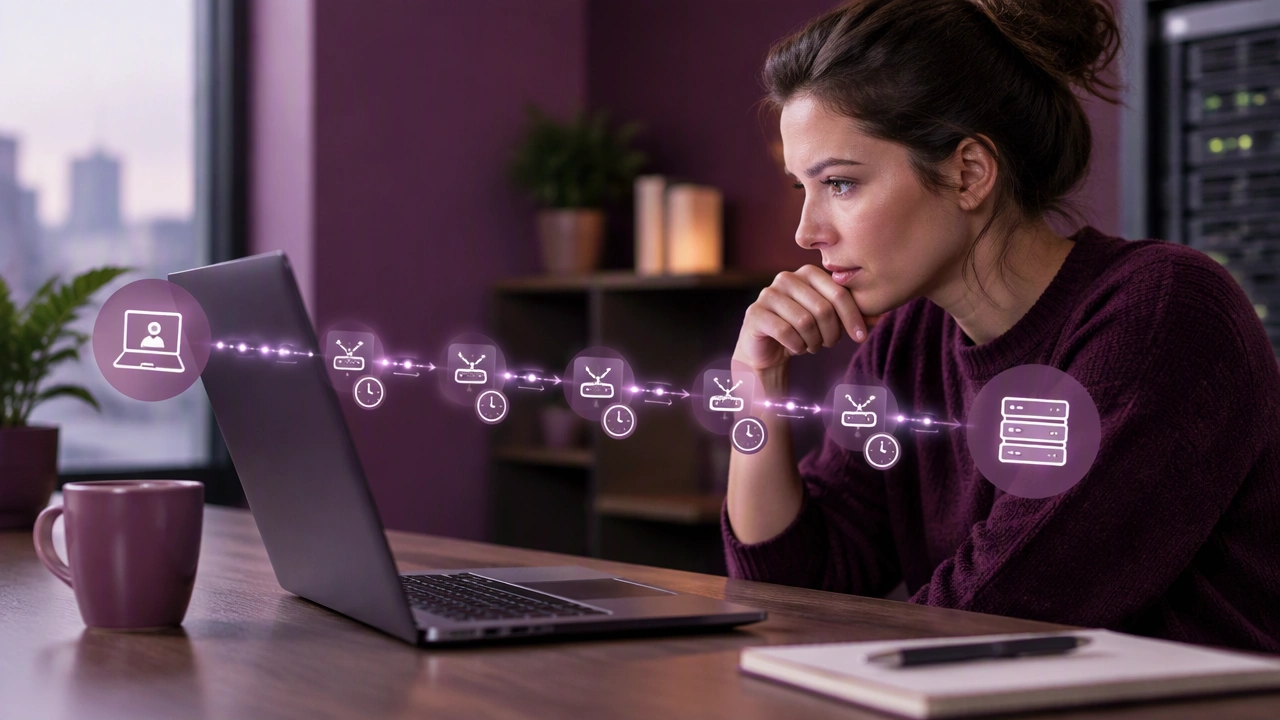
Network latency is often measured in milliseconds, and many teams treat it as negligible. A 2 ms delay between two services sounds trivial in isolation. But modern user-facing flows are not isolated. They are dependency chains. If a page render requires five sequential service calls, and each adds 2 ms of network time plus processing, the network portion alone becomes meaningful. If those five calls also fan out to additional dependencies, the total network time grows again.
There are several reasons small delays multiply quickly:
- Sequential dependencies: When service B waits for service A, and service C waits for service B, network latency adds up across the chain.
- Fan-out patterns: A single request may call several services in parallel. Even if each call adds only a few milliseconds, the overall latency is often bound by the slowest one.
- Retries and timeouts: When a call is slow or fails, retries add more network round trips and extend tail latency.
- Shared infrastructure: Network switches, load balancers, and proxies add small per-hop delays that scale with request volume.
- Cold paths: DNS lookups, TLS handshakes, and connection establishment can add tens or hundreds of milliseconds on the first request or after idle periods.
These effects are often invisible in simple averages. The system may look healthy on dashboards that show mean response time, while users experience slow page loads caused by the long tail.
Where latency hides in a typical request
To see the hidden cost, it helps to trace where network time appears in a typical web request.
- Client to edge: The browser or mobile app connects to a CDN or load balancer. Latency here depends on geography, last-mile quality, and TLS negotiation.
- Edge to application server: The request crosses into the internal network. This path may include multiple network devices and virtualization layers.
- Application to service mesh: In Kubernetes or service-mesh environments, sidecars or ingress controllers add extra hops.
- Service to database or cache: Database connections often cross availability zones or subnets, adding latency even inside the same data center.
- Service to third-party APIs: External calls are outside your control. Their latency varies and can spike without warning.
Each hop is small on its own. Together, they form the hidden tax on every user request.
Why averages hide the problem
Latency problems are usually tail problems. If 95% of requests complete in 120 ms, but 5% take 800 ms, many users still have a poor experience. Averages and even medians can mask this. Long-tail latency is often caused by:
- GC pauses that hold connections open
- Connection pool exhaustion that forces new TCP or TLS setups
- Network congestion on shared links
- Slow dependencies that occasionally time out
- Packet loss or retransmissions on unstable paths
Because these causes are intermittent, they show up clearly in percentile distributions but poorly in simple averages.
How to see network latency clearly
Seeing latency requires instrumentation at multiple layers. The goal is to separate network time from processing time and to track both per hop and end to end.
1. Instrument at the service level
Every service should record time spent waiting for downstream calls. This includes connection time, time to first byte, and total call duration. These metrics should be tagged with the target service, operation, and status code.
2. Use distributed tracing
Tracing makes dependency chains visible. A single trace shows where time is spent across services and network boundaries. Traces are especially useful for identifying fan-out patterns and slow paths that are hard to spot in aggregate metrics.
3. Capture DNS, TCP, and TLS timings
Many teams measure only total request time. To see network latency clearly, capture DNS resolution time, TCP connect time, and TLS handshake time. These values explain cold-start delays and intermittent slowness caused by connection churn.
4. Monitor percentile distributions
Track p50, p95, p99, and p99.9 for request latency and for individual downstream calls. Tail metrics expose the hidden cost that averages hide.
5. Measure network-layer signals
Complement application metrics with network metrics: packet loss, retransmissions, interface errors, link utilization, and buffer drops. These signals often correlate with latency spikes in application logs.
6. Add synthetic monitoring
Synthetic tests run from multiple locations and measure end-to-end latency without relying on real user traffic. They provide a baseline and can reveal regional or path-specific issues.
Practical techniques to reduce the hidden cost
Once you can see latency, you can reduce it. The most effective strategies focus on cutting unnecessary round trips and making the remaining ones faster and more stable.
- Batch and coalesce calls: Reduce the number of network hops by combining related operations.
- Cache aggressively at the edge: Serve repeated content from locations closer to users.
- Reuse connections: Keep-alive, HTTP/2 multiplexing, and connection pooling avoid repeated TCP and TLS setup costs.
- Move computation closer to data: Reduce cross-zone or cross-region calls when latency-sensitive logic depends on a specific dataset.
- Set realistic timeouts and budgets: Propagate time budgets through the call chain so one slow dependency does not consume the entire request budget.
- Use circuit breakers and fallbacks: Prevent slow paths from blocking unrelated work.
- Tune DNS and TLS: Use local DNS caching, long-lived TLS sessions, and modern ciphers to reduce handshake overhead.
A short case example
Consider a checkout flow that calls five internal services and two third-party APIs. In production, the average response time looks fine. However, p99 is high. After adding tracing and DNS/TCP/TLS timings, the team discovers that one internal service occasionally opens new database connections because the pool is exhausted. Each new connection adds a TCP handshake and a TLS setup, plus a DNS lookup when the database endpoint is resolved again. The extra network time is small per call, but it happens on the slowest requests, pushing them into the long tail. By increasing the connection pool, reusing connections more consistently, and caching DNS results locally, the team reduces p99 latency significantly without changing business logic.
Key takeaways
- Small network delays multiply across dependencies and become a hidden cost on every user request.
- Averages often hide tail latency. Use percentile distributions to see the real user experience.
- Instrument services, traces, and network metrics together to separate network time from processing time.
- Reduce round trips, reuse connections, and move work closer to the data to cut latency at the source.
Network latency is not just a low-level detail. It is a core factor in system performance and user experience. By measuring it carefully and reducing unnecessary hops, teams can remove a hidden tax that affects every request their systems handle.