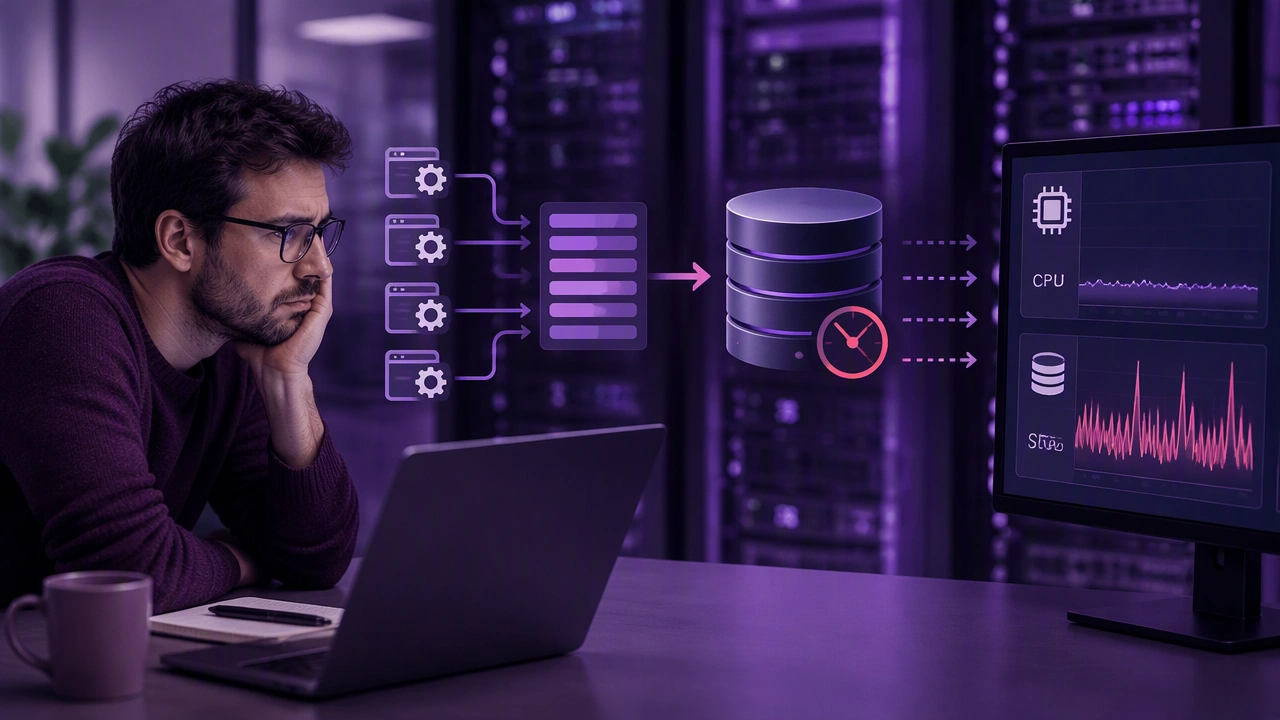
Storage I/O Contention Explained: Why Applications Stall While Processors Look Idle
When an application slows down, many teams check CPU first. If the processors look relaxed, the assumption is that the server is fine. That assumption can be costly. A busy database, a file-heavy web application, or a batch job can stall for seconds while CPU charts stay quiet. The hidden culprit is often storage I/O contention, and once you understand it, the symptoms become much easier to read.
This article explains why storage queues build up, how they affect applications, and how to see them early enough to act. The goal is practical: help you connect user-visible slowdowns to the storage layer with clear signals you can measure.
What storage I/O contention actually means
Every read or write to disk has to travel through a path. The application thread sends a request, the operating system places it in a queue, the storage controller accepts it, and the device returns the result. Contention happens when multiple workloads compete for that path at the same time. Requests wait in line, and the application pauses until its turn comes.
Even on fast SSDs, queuing still matters. NVMe drives are quick, but they are not infinite. When many processes issue reads and writes at once, the device reaches its limit, and latency rises. With spinning disks, the effect is even stronger because seek time and rotational delay add up quickly.
The key point is that the application does not see disk speed directly. It sees the time between sending a request and receiving a response. If that time grows, threads block, connections pile up, and users feel the slowdown.
Why processors look idle while the application waits
Most application servers are event-driven or thread-pooled. When a thread asks for data from storage, it goes to sleep until the operating system wakes it up with the result. While it sleeps, the CPU is free to run other work. If enough threads are sleeping on storage, the CPU may look lightly loaded, but the application is not progressing.
This is why CPU utilization is not a complete health indicator. A server can run at 30% CPU and still have users reporting timeouts. The useful metric is not how busy the processors are, but how many application threads are waiting for I/O and how long those waits last.
Common signs of storage queuing in applications
- Request latency spikes: Response times jump even though CPU and memory look normal.
- Connection pool pressure: Database or HTTP connections stay occupied longer, causing new requests to wait or fail.
- Thread pool saturation: Worker threads are all busy, but CPU is not high because they are blocked on I/O.
- Batch job slowdowns: Jobs that process files or rows take longer when other workloads share the same disks.
- Intermittent freezes: Short pauses appear at random, often during peaks or when background tasks run.
These symptoms are easy to misread. Teams often add more CPU or memory, but the real fix is to reduce the time threads spend waiting for storage.
How to see storage queues before users complain
Visibility starts with the right measurements. You want to observe both the device and the operating system, because each view tells a different part of the story.
Measure latency at the OS level
On Linux, tools like iostat, iotop, and pidstat can show per-device and per-process activity. Look at average wait time and how long requests stay in the queue. On Windows, Resource Monitor and Performance Monitor provide similar views for disk queue length and average response time. Track these values over time, not only during incidents.
Watch queue depth and saturation
Queue depth shows how many requests are waiting at the device. When queue depth climbs and stays high, the device is saturated. If latency also rises, you are seeing real contention. If latency stays low while queue depth grows, the device still has headroom.
Correlate with application metrics
Connect storage signals with application signals. Compare disk latency with request latency, database query duration, and thread pool usage. When all of them move together, storage is likely the bottleneck. If only one moves, look elsewhere first.
Check file system and journal activity
Heavy logging, temporary file creation, and database journals can add hidden writes. A single misconfigured log level can push a system from healthy to saturated. Audit which processes write the most and when those writes happen.
Why contention appears suddenly
Storage contention often shows up after a change that looks harmless. A new reporting job runs at the same time as user traffic. A backup starts without throttling. A monitoring agent scans large directories. A software update changes how often data is flushed to disk.
Contention can also appear because of growth. More users, more records, and more files mean more I/O. A system that was fine last quarter can be on the edge today. Capacity planning should include IOPS and throughput, not just space.
Practical ways to reduce storage I/O contention
- Separate workloads: Place databases, logs, and batch data on different volumes or devices when possible. This reduces competition for the same queue.
- Tune the application: Use efficient queries, fetch only needed columns, and avoid repeated small reads. Small improvements at the query level can cut I/O sharply.
- Batch and throttle: Schedule heavy jobs outside peak hours or add rate limits. A steady, controlled flow is better than a burst that saturates the device.
- Use caching: Read caching reduces repeated reads. Write caching with proper durability controls can smooth bursts. Be careful with cache consistency and failure handling.
- Upgrade the right part: Sometimes the fix is a faster device, but often it is better queue management, improved file system settings, or a controller firmware update.
- Monitor continuously: Set alerts on latency and queue depth, not only on disk space. Early warnings give you time to act before users are affected.
A simple way to explain the problem to non-technical stakeholders
Imagine a coffee shop with one counter. Even if the barista is fast, a long line of orders makes customers wait. The barista may look busy, but the real issue is the queue. Storage works the same way. The device may be fast, but if too many requests arrive at once, the line grows and the application stalls.
When you frame the issue as a queuing problem, decisions become clearer. You can reduce the number of orders, add another counter, or set priorities so important orders go first.
Key takeaways
- CPU is not the whole story: Idle processors can hide deep storage waits.
- Queues cause application pauses: High latency and saturation are the real signals.
- Measure both sides: Watch the device and the application together.
- Control the flow: Throttle background work, tune queries, and separate competing workloads.
- Monitor over time: Trends reveal risk before incidents appear.
When you learn to read storage queues, many mysterious slowdowns become straightforward. You stop guessing and start connecting user impact to a clear, measurable cause. That shift makes performance work calmer and more effective, even in complex environments.